
AI Crawler Checker
Is Your Site Blocking the AI Crawlers That Matter?
KinetixSEO is a free AI crawler checker, part of its SEO and AI-citation (GEO) checker — paste a URL and see, per bot, whether GPTBot, ClaudeBot, PerplexityBot, Google-Extended, and 50+ other named AI crawlers are allowed or blocked — a page you never see can never be cited.
What you get
Every dimension of GEO Readiness, including crawler access
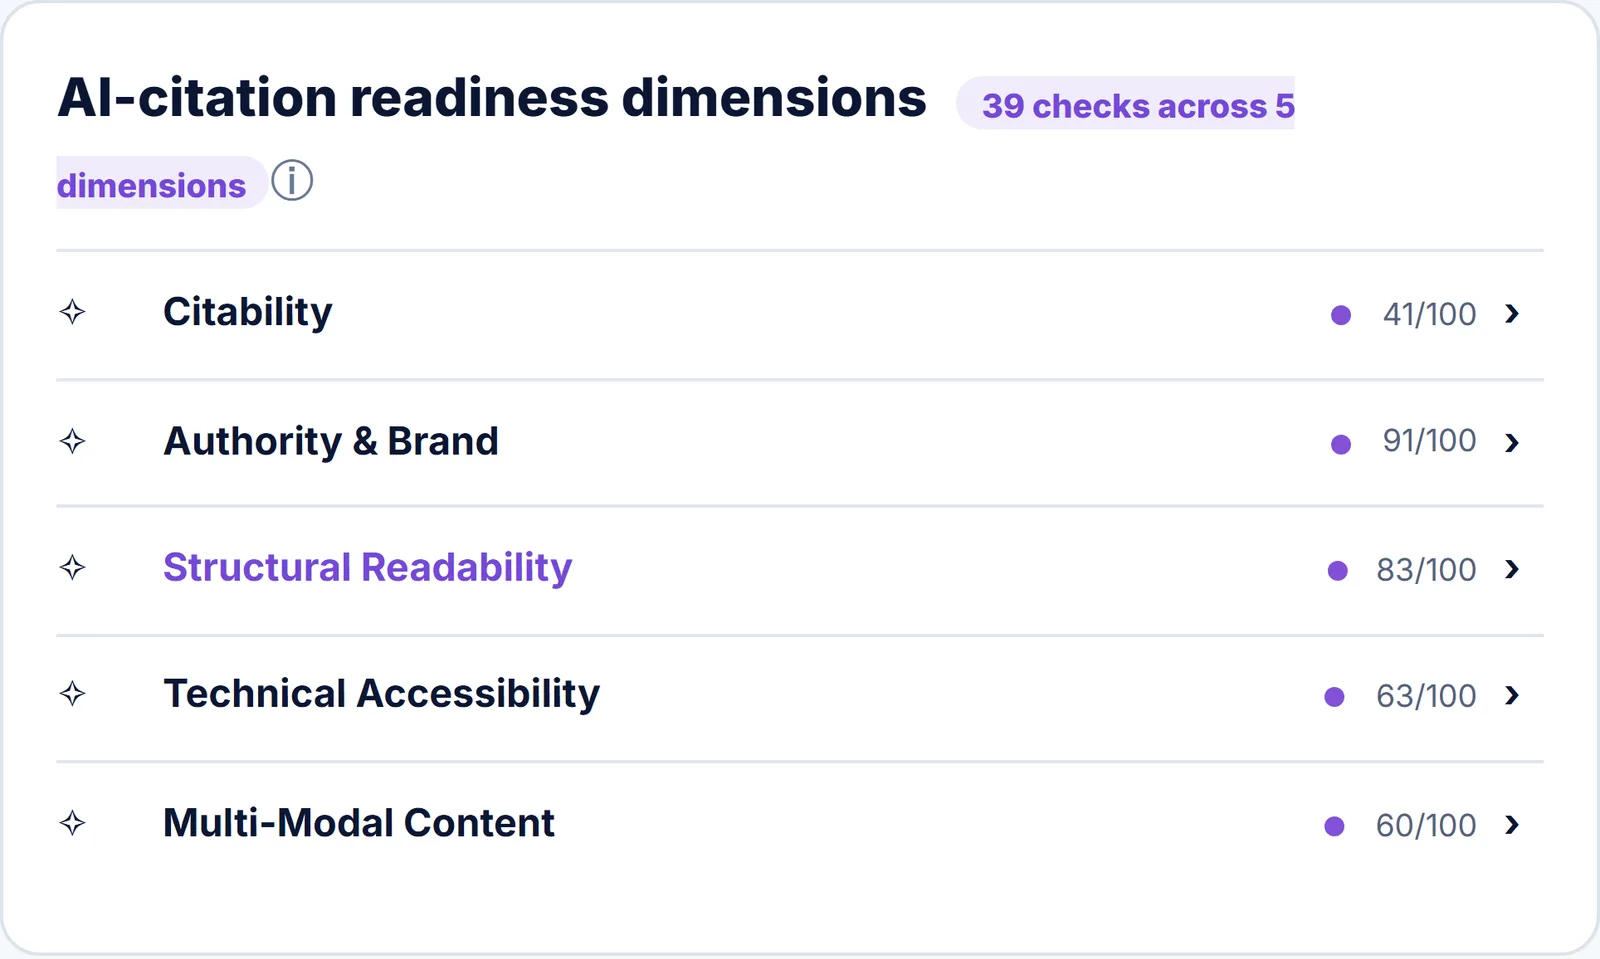
Technical Accessibility is one of five weighted dimensions behind the GEO Readiness Score (20%) — see the GEO Audit Tool for the full breakdown.
Training, search, and live-fetch bots are different
Not every AI bot does the same job
Not every AI bot does the same job, so a block on one means something different than a block on another, even though robots.txt shows both simply as disallowed. Blocking a training-only crawler, such as Applebot-Extended, affects a future model, not today's answers, because it only gathers material for a model not yet built. Blocking a search-indexing crawler, such as OAI-SearchBot, can remove a page from a future AI answer before that answer is ever generated. Blocking a live-fetch crawler, such as ChatGPT-User, can remove a page from an answer being generated right now, for a real user, in this exact moment, with the effect felt immediately rather than later. The checker lists every one of the 53 bots it checks with its own allowed or blocked status, then counts the fully blocked ones in two groups — citation bots, the search-indexing and live-fetch crawlers behind answers being generated now, and training bots, which only feed future models — so a block reads as something specific and actionable instead of just "blocked," with no way to tell what type of visibility was actually lost.
What this doesn't do
Crawler access is a prerequisite for AI visibility, not a promise of it — an allowed bot still has to decide a page's content is worth citing over the alternatives it also fetched. This reports what robots.txt currently allows across 53 named AI-bot user agents; it does not and cannot observe or influence how any AI system ranks or selects content once that system can already reach it.
FAQ
AI crawler checker — FAQ
Which AI crawlers does this check? +
This checker reads your robots.txt against 53 named AI-bot user agents and reports which are allowed and which are blocked, per bot, rather than giving one pass/fail verdict for the whole file. That list spans OpenAI (GPTBot, ChatGPT-User, OAI-SearchBot), Anthropic (ClaudeBot, Claude-SearchBot, Claude-User), Google (Google-Extended, Google-NotebookLM), Perplexity, Microsoft's bingbot (which Copilot Search cites from), Meta (Meta-ExternalAgent, Meta-WebIndexer), Amazon, Apple, ByteDance's Bytespider, Huawei's PetalBot, You.com, DeepSeek, and the retrieval APIs that third-party agents ground answers in, among 53 tracked names in total, covering training crawlers, search-index crawlers, and live-fetch agents alike. None of these bot names show up in a plain robots.txt read, since most files list only a handful of rules by name — you have to check the file against each specific user-agent string, one by one, to see who is actually allowed through and who is quietly shut out.
Why does it matter whether a bot trains, searches, or fetches live? +
Blocking a training-only crawler, such as Applebot-Extended, affects a future model rather than an answer being shown today, because that bot only ever collects material for a model that has not been built yet. Blocking a search or live-fetch crawler, such as OAI-SearchBot or ChatGPT-User, can remove a page from an AI answer being generated right now, for a real user, in this exact moment, with no delay before the effect is felt. The checker lists every one of the 53 bots it checks with its own allowed or blocked status, then counts the fully blocked ones in two groups — citation bots, which are the search-index and live-fetch crawlers behind answers being generated now, and training bots, which only feed future models — so a block tells you which kind of visibility you are losing rather than leaving 'blocked' as a single vague, undifferentiated warning. A handful of retrieval-API agents and retired crawler names are still listed per bot but counted in neither group, because blocking one of them does not cleanly remove a page from any named answer engine. Fixing the wrong block first wastes effort on a crawler that was never going to change today's answers anyway, while the crawler actually costing visibility right now stays blocked.
Why would a bot be blocked without me knowing? +
Most often it is a blanket "Disallow: /" left over from a staging environment that never got removed after launch, a security plugin's default bot-blocking rule written before AI crawlers existed as a category worth naming, or a wildcard rule meant for ordinary scrapers that catches AI bots by accident along the way. A migration to a new host or CMS can also silently reset robots.txt to a restrictive default during the switch. None of these show up by reading robots.txt casually, since the file often looks short and harmless at a glance — they only surface when it is checked against each of the 53 specific AI-bot user-agent strings this tool looks for, one at a time, rather than skimmed for a single blanket rule at the top of the file that looks like it only targets old-style scrapers.
Is AI crawler access the same as AI visibility? +
No — crawler access is a prerequisite for AI visibility, not a promise of it. A blocked crawler can never cite a page it was never allowed to fetch in the first place; an allowed one still has to decide the content is worth citing over a competitor's page that answers the exact same question just as well or better, and access alone says nothing about how that later decision goes. AI crawler access falls under Technical Accessibility, one of five weighted dimensions in the GEO Readiness Score at 20% weight, alongside Citability (25%), Authority & Brand Signals (20%), Structural Readability (20%), and Multi-Modal Content (15%) — see the GEO Audit Tool for the full breakdown across all five and where a specific page is currently losing the most points toward the other four.
Is the AI crawler checker free? +
Yes — paste a URL and get the full per-bot allow/block breakdown across all 53 checked crawlers with no signup, as part of the same free check as the GEO Readiness Score.
Test your AI crawler access
Free, no signup — paste a URL and see the full per-bot breakdown in a minute.